Next.js Architecture: How to Build an App That's Still Fast in Year Three
Almost every Next.js rescue project I've been handed starts with the same sentence: "It was really fast when we launched."
And it was. A fresh Next.js app is fast in the way an empty flat is spacious. Then a year passes. Someone adds a client-side state library at the root layout to fix a theme flicker. Someone else wires an analytics script into the same layout because it was the easiest place to put it. A dashboard component needs a chart, so a 300KB charting library lands in the shared bundle. A marketing page imports a helper from the dashboard, which imports the database client, which pulls the whole ORM into a page that shows three paragraphs of text. Nobody did anything obviously wrong. Every commit passed review. And the app that scored 98 on Lighthouse at launch now takes four seconds to become interactive on a mid-range Android phone over a patchy connection.
That is what an architecture problem looks like in practice. It is never one bad decision. It's the absence of a small set of deliberate ones, made early, that the next hundred commits are obliged to respect.
This guide is about those decisions. Not a tour of the framework's features — the official docs do that better than any blog post can — but the architectural choices that determine whether your Next.js app is still cheap to change in year three. I've been building production web applications since 2018, and the patterns below come from shipping and then maintaining them, which is where architecture actually gets tested.
At a glance
- Next.js architecture is four decisions, not a folder layout. How each route renders, where the server/client boundary sits, how data is accessed, and what gets cached. Everything else is downstream of those four.
- Choose a rendering strategy per route, not per app. A marketing page, a product listing and a logged-in dashboard have nothing in common, and forcing them into one strategy is the most common cause of both slow pages and stale data.
"use client"is a bundle decision. It doesn't mean "this is interactive" — it means "everything this imports ships to the browser." Push it to the leaves of your tree, never the root.- Give data access one front door. A single typed data layer that owns queries and authorisation checks prevents the slow scatter of
SELECTstatements and half-remembered permission checks across two hundred files. - Caching in Next.js 16 is explicit and opt-in. Cache Components,
use cache,cacheLifeand tag-based invalidation replaced the implicit caching that used to surprise people. This is a large improvement, and it requires an actual plan. - Performance is architectural, not cosmetic. LCP under 2.0s, CLS under 0.05 and INP under 200ms are decided by your rendering and bundle strategy, not by compressing images at the end.
- Budget honestly. A well-architected Next.js build runs ₹1.2–3.5 lakh (
$1.4k–$4.2k) for a marketing site, ₹4–12 lakh ($4.8k–$14k) for a real application, plus 15–20% of build cost a year to stay healthy. - You can migrate incrementally. Route-by-route, behind a proxy, with the old system live throughout. Big-bang rewrites are how good products die.
What "architecture" actually means in a Next.js app
Ask ten developers about Next.js architecture and eight will describe a folder structure. Folder structure matters, but it's the output of architecture, not the thing itself. Architecture is the set of decisions that are expensive to reverse.
In a Next.js App Router codebase there are exactly four of those, and they compound:
- Rendering — for each route, is the HTML built at build time, at request time, or streamed in pieces? This decides your speed ceiling and your freshness floor.
- The server/client boundary — which components run only on the server, and which ship JavaScript to the browser? This decides your bundle size, which decides your interactivity.
- Data access — who is allowed to talk to the database or an external API, and through what? This decides your security posture and your ability to refactor.
- Caching and invalidation — what is stored, for how long, and what event makes it stale? This decides your infrastructure bill and your correctness.
Get those four right and a messy folder structure is a weekend of tidying. Get them wrong and the tidiest folder structure in the world won't save you, because the problem is distributed through every file.
 A diagram sketched on a whiteboard during a working session — the rendering, boundary, data and cache decisions are worth an hour of argument before they're worth a line of code
Decision 1: Rendering strategy, chosen per route
The single most valuable habit in App Router work is refusing to answer the question "is this app static or dynamic?" It's the wrong unit. The right unit is the route.
Next.js gives you a spectrum, and a mature architecture uses most of it in the same codebase:
- Fully static — rendered once at build time, served from the CDN. Nothing is faster. Marketing pages, blog posts, service pages, documentation.
- Static with revalidation (ISR) — static, but regenerated in the background on a schedule or when you invalidate a tag. Product catalogues, listings, anything where "a few minutes old" is fine.
- Streamed / partially prerendered — a static shell ships immediately while slower, personalised parts stream in behind Suspense boundaries. The user sees layout and content in under a second even though a slow query is still running.
- Fully dynamic — rendered per request. Anything that depends on the session, cookies, headers or real-time data.
- Client-rendered islands — small interactive widgets hydrated in the browser inside otherwise server-rendered pages.
Next.js 16 made this considerably cleaner. The old experimental ppr flag is gone, replaced by Cache Components (cacheComponents: true in next.config.ts). The model inverted: everything is dynamic by default and executes at request time, and you opt into caching with the "use cache" directive on a page, component or function. Partial prerendering is the default behaviour of that model rather than a separate feature you switch on.
That inversion is the right one. The old implicit caching was the single biggest source of "why is this data stale?" bug reports in App Router codebases. Explicit is slower to write and far cheaper to own.
Here's how I map route types in a typical build:
| Route type | Strategy | Why |
|---|---|---|
| Home, services, about, blog | Fully static | Zero server cost, instant LCP, ideal for search |
| Blog and portfolio detail pages | Static, generated from content files at build | Content changes with a deploy, so nothing needs to be dynamic |
| Product or listing pages | Cached with tag invalidation | Fast like static, updated the moment inventory changes |
| Search results, filtered views | Dynamic, streamed | Depends on the query, but the shell and filters can render instantly |
| Authenticated dashboard | Dynamic, streamed, with a cached shell | Layout and navigation are the same for everyone; only the data is personal |
| Account settings, checkout | Fully dynamic, never cached | Correctness beats speed, and the cost of a stale value is real money |
| API and webhook routes | Dynamic, uncached | They exist to have side effects |
The failure mode here is uniformity in either direction. Teams that make everything dynamic pay for server rendering on pages that never change and wonder why their hosting bill scales with traffic. Teams that make everything static end up with a "refresh to see your changes" caveat in their support docs. Choose per route, write the choice down, and make it visible in code review.
This is also where the website versus mobile app question quietly resolves itself for a lot of businesses: a well-architected Next.js app with a static shell and streamed data feels close enough to native that a separate app becomes a choice rather than a necessity.
Decision 2: Where the server/client boundary sits
This is where most Next.js codebases actually go wrong, and it's subtle because the mistake is invisible in the browser. The page looks fine. It's just heavier than it should be, and it gets heavier every sprint.
React Server Components run on the server only. They can query a database directly, read secrets, and render to HTML without shipping a single byte of their own logic to the browser. Client Components run in both places: they render on the server for the initial HTML, then ship to the browser and hydrate so they can handle interaction.
The rule people learn is "add "use client" when you need state or an event handler." That's true but incomplete. The complete version is:
"use client"marks a boundary, not a component. Everything imported below that boundary — every utility, every date library, every icon set, every constant file that happens to import something heavy — becomes part of the browser bundle.
So the architectural instruction is: push the boundary as far down the tree as it will go.
In practice:
- A page that displays data and has one interactive button is a Server Component that renders a small Client Component, not a Client Component that fetches data.
- A layout should almost never be a Client Component. If you need a theme toggle in the header, the toggle is a client island; the header is not.
- Interactive wrappers should accept server-rendered content as children. A client-side accordion or tab set can wrap server-rendered children without dragging their imports into the bundle, because children are passed as already-rendered React elements, not imported modules.
- Props crossing the boundary must be serialisable. Functions, class instances and database models can't cross. If you find yourself wanting to pass a function down, the boundary is in the wrong place.
The practical test I use in review: open the route's bundle analysis and ask what the largest three modules are and why the browser needs them. Nine times out of ten, one of them is there by accident — a formatting helper imported from a barrel file that also exports something enormous. Barrel files (index.ts re-exporting a whole directory) are the single most common cause of accidental bundle bloat in Next.js projects. Import from the specific module instead.
 Code on a dark screen — the server/client boundary is the most consequential line in a Next.js codebase, and it's one directive long
None of this is theoretical. On the Steri360 rebuild and the GOC inventory platform, the difference between "loads instantly on a phone in Srinagar" and "spins for four seconds" was almost entirely a boundary question — not server capacity, not image weight, not the database.
Decision 3: One front door for data
Here's a pattern I see constantly in App Router codebases that started well: because Server Components can query the database directly, every page starts querying the database directly. Six months later, the same query exists in nine slightly different forms, three of them have a subtly different permission check, and one of them has none at all.
The fix is a data access layer — a small set of modules that are the only code in your application permitted to touch the database or an external API. Everything else calls into them.
A data layer should own four things:
- The queries themselves, typed end to end, so a schema change surfaces as a TypeScript error rather than a runtime surprise in production.
- Authorisation. Every function verifies the session and the caller's right to the specific record inside the function, not in the page that calls it. Checks in pages get forgotten; checks in the data layer cannot be bypassed by a new route.
- Shaping. The layer returns exactly what the UI needs — a view model, not a raw database row. This stops internal columns from leaking into a client payload, which is a real and common data exposure.
- Caching policy. Which queries are cached, under which tags, for how long. Keeping it here rather than in components means you can reason about your whole cache in one directory.
Three rules that go with it:
- Never call your own API route from a Server Component. It is an HTTP round trip to your own process to run a function you could have called directly. It adds latency, breaks type safety and doubles your error surface. API routes exist for external consumers, webhooks and client-side mutations.
- Fetch where you render, not at the top. Prop-drilling data from a page into a component five levels down couples them permanently. React deduplicates identical requests within a single render pass, so a component fetching what it needs is usually free.
- Mutations go through Server Actions with validation at the boundary. Validate input with a schema on the server — never trust the client's validation, which exists for user experience, not security.
This is the layer that separates a codebase you can hand to another developer from one only its author can safely change. When I build custom business software — inventory systems, billing, multi-tenant SaaS — this is the part that gets designed first, on paper, before any UI exists. The Kapda Stock textile platform and the MedStore pharmacy ERP both live or die on it.
Decision 4: A caching model you can explain out loud
If you can't describe your caching in three sentences, you don't have a caching strategy — you have caching incidents waiting to happen.
Next.js 16 gives you genuinely good tools here, and they reward a plan:
"use cache"marks a page, component or function as cacheable. The compiler generates the cache key from the inputs, which removes an entire category of hand-rolled key bugs.cacheLifesets how long an entry stays fresh, using built-in profiles likemax,hoursanddays, or a custom profile you define once in config.cacheTaglabels an entry so you can invalidate it by meaning rather than by URL — tag everything touching a product with that product's id, and one invalidation reaches every page showing it.revalidateTag(tag, profile)invalidates with stale-while-revalidate behaviour: the next visitor gets the cached copy immediately while the refresh happens in the background. Note the second argument — the single-argument form is deprecated in Next.js 16.updateTag(tag), in Server Actions, gives read-your-writes semantics: the user who just edited something sees their change immediately rather than an old copy.refresh()refreshes uncached data only, for things like a notification count, without disturbing your cached shells.
Layer those deliberately. A working mental model for most applications:
| Layer | What it holds | Invalidated by |
|---|---|---|
| CDN / static | Marketing pages, blog, assets | A deploy |
| Full route cache | Listings, catalogue, public detail pages | A tag, when the underlying record changes |
| Data layer cache | Expensive queries, third-party API responses | A tag or a time profile |
| Request memoisation | Repeated identical reads in one render | Automatically, per request |
| Nothing | Sessions, carts, balances, anything personal | Not applicable — never cache it |
Two rules keep this honest. First, default to not caching anything personal. The worst bug in this category is not a stale page; it's one user seeing another user's data because something session-dependent got cached at the route level. Second, invalidate on the write, not on a timer. Time-based expiry is a guess. Tagging the write path means the cache is correct by construction and you can then set generous lifetimes without fear.
 Network cabling glowing in a dark rack — caching is where a Next.js app's speed and its correctness are traded against each other, so the trade should be written down
Where the code lives: structure that survives a team
Now the folder structure — which is much easier once the four decisions are made.
The default instinct is to group by type: all components in components/, all hooks in hooks/, all utilities in lib/. That works beautifully up to about fifteen files and becomes actively hostile after that, because a single feature is smeared across six directories and no one can delete anything with confidence.
A structure that scales groups by feature and keeps the routing tree thin:
app/holds routing and nothing else — pages, layouts, loading, error and not-found boundaries. Route groups (parenthesised folders) separate concerns like marketing and dashboard without adding URL segments. A page file should be short: it resolves params, calls the data layer, and composes feature components.features/ormodules/holds one folder per business capability — billing, inventory, auth, orders. Inside each: its components, its data access, its validation schemas, its types. A feature is a thing you can read in one sitting and delete in one commit.components/ui/holds genuinely generic primitives — button, dialog, input, card. If it knows what an invoice is, it doesn't belong here.lib/holds cross-cutting infrastructure: the database client, the mail client, environment parsing, shared utilities. Small, boring and stable.content/holds MDX or CMS-sourced content when the site is content-driven, so editorial changes never require touching application code.
Two conventions do most of the work: colocate until it's shared twice (the first duplication is cheaper than the wrong abstraction), and no cross-feature imports (if billing needs something from inventory, it goes through a defined interface or moves to shared). That second one is the difference between a codebase where a new developer can work safely in week one and one where every change is a guess.
Environment variables deserve a mention because they cause so many production incidents. Parse them once, at startup, through a schema, and fail the boot if something required is missing. A typo in a variable name should break the build, not surface as a silent undefined in a payment call at 11pm.
 Labelled archive boxes stacked on shelves — a good project structure isn't about tidiness, it's about being able to find and delete things without fear
Layouts, streaming and the shape of a page
The layout tree is an architectural artefact people rarely treat as one. Layouts persist across navigations and don't re-render, which is exactly why putting too much in them is so costly: whatever you add to the root layout is paid for on every single page of the site, forever.
Keep the root layout minimal — HTML shell, fonts, theme provider, global styles. Put navigation, sidebars and headers in route group layouts, so the dashboard's chrome isn't loaded by someone reading a blog post.
Then use the boundary files properly, because each one is a real user experience decision:
loading.tsxis a Suspense boundary for the route. It should render a skeleton that matches the real layout's dimensions — a matching skeleton keeps CLS near zero, while a centred spinner guarantees a layout shift when content arrives.error.tsxcatches render errors in its segment and must be a Client Component. A good one explains what failed in human language and offers a retry. A generic "Something went wrong" is a support ticket with extra steps.not-found.tsxhandles missing records, and on a content site it's a genuine SEO asset — a 404 that offers relevant links recovers traffic that a dead end loses.- Nested Suspense boundaries let you stream. Wrap the slow part — a report, a recommendations widget, a third-party feed — so the rest of the page paints immediately. This is the single highest-leverage performance technique in the App Router, and it's almost free.
The design question underneath all of this is what should the user see at 200ms, at 600ms, and at two seconds? Answer that per page and the boundaries place themselves.
Performance is an architectural property
You cannot optimise your way out of an architecture problem in the week before launch. By then the bundle is the bundle. But if the four decisions are right, hitting the targets is mostly discipline:
- LCP under 2.0s — the largest element must be in the initial server-rendered HTML. That means no fetching the hero content on the client, no hero image behind a lazy loader, and a
priorityflag on the one image that matters. - CLS under 0.05 — explicit dimensions on every image and embed, skeletons that match final dimensions, fonts loaded with
next/fontso there's no swap jump, and no content injected above existing content after paint. - INP under 200ms — fewer hydrated components means less main-thread work. This is the boundary decision showing up as a user-facing metric.
- JavaScript budget — set a number for first-load JS per route and fail the build when it's exceeded. A budget nobody enforces is a wish.
- Images —
next/imagewith AVIF and WebP, correctsizes, and remote patterns allow-listed. Note that Next.js 16 changed the defaultimages.qualitiesto a single value and raised the minimum cache TTL to four hours, both of which reduce cost. - Third-party scripts — the honest audit. Analytics, chat widgets, pixels, embeds and tag managers routinely cost more than the entire application. Load them after interaction, gate them behind consent, and remove the ones nobody reads.
The reason to care isn't a score in a tool. On a typical Indian mobile connection, a page that becomes interactive in 1.5 seconds and one that takes 5 seconds convert differently by a margin that dwarfs anything a redesign will do — which is why performance work belongs in the same conversation as SEO strategy rather than in a separate backlog.
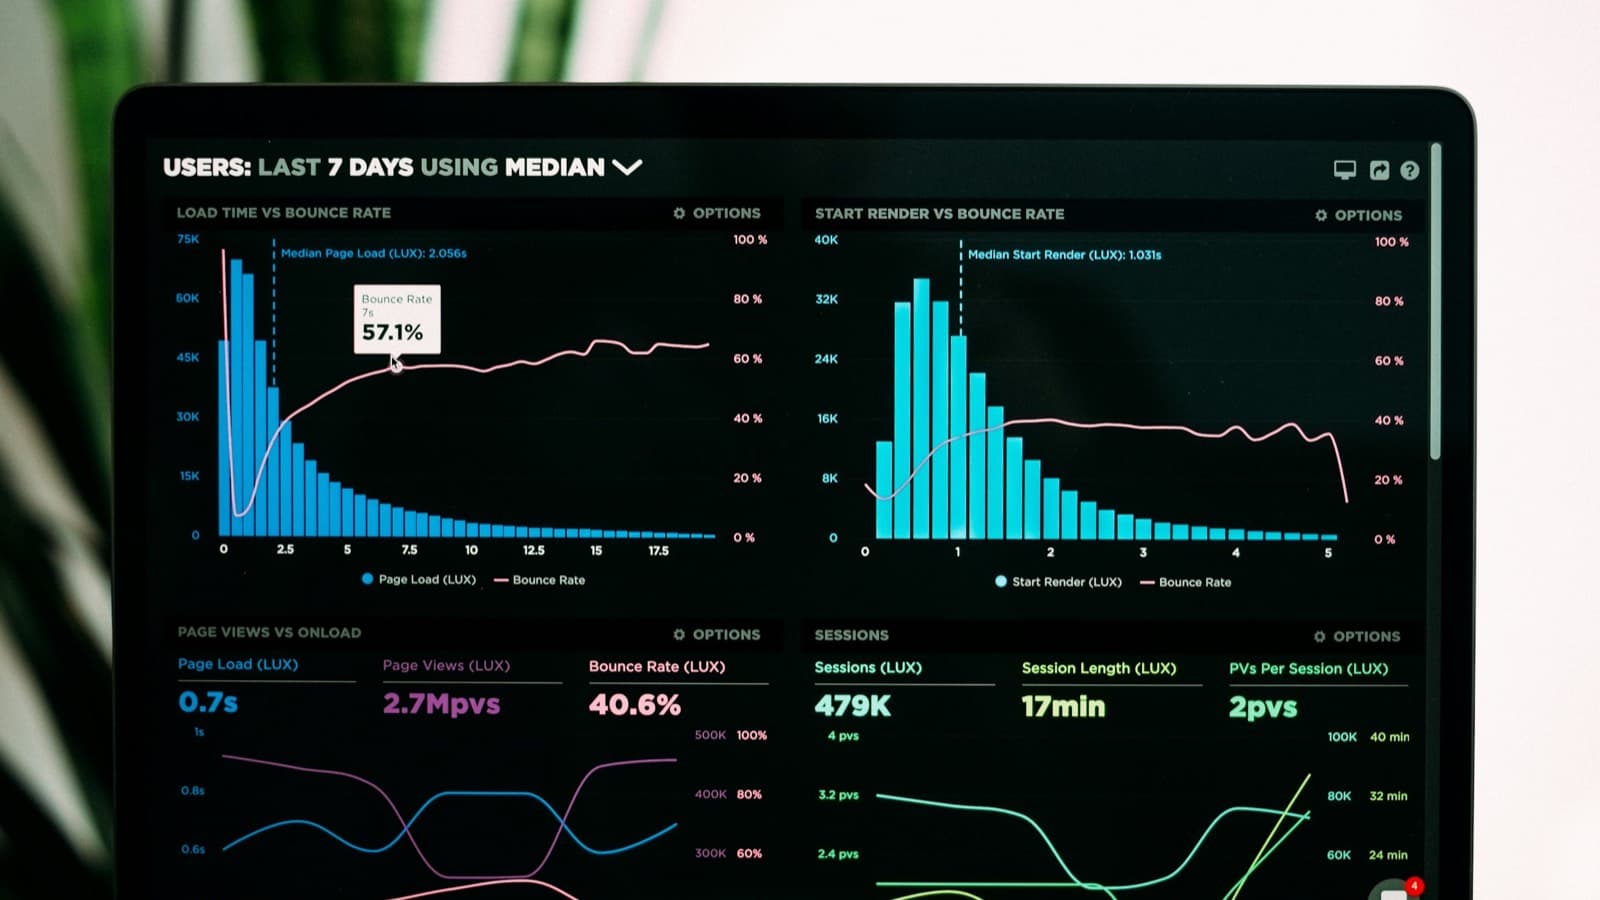 A dark analytics dashboard showing performance graphs on a laptop — Core Web Vitals are the output of architectural decisions made months earlier
SEO architecture, not SEO cleanup
For any site that needs to be found, search architecture is part of the build, not a phase afterwards:
- Metadata per route via
generateMetadata, with a unique title under 60 characters, a description under 155, and a canonical URL on every page. Note that in Next.js 16paramsandsearchParamsare async and must be awaited. - Structured data as JSON-LD, emitted by a single component so it can't drift:
OrganizationorLocalBusinesssitewide, plusService,BreadcrumbList,BlogPosting,ProductorFAQPagewhere they apply. - A generated sitemap and robots file driven by the same data that generates your routes, so a page can never exist without being listed or be listed without existing.
- Dynamic Open Graph images rendered at the edge from the page's own title, so every share looks deliberate.
- Internal linking as information architecture — services linking to relevant work, work linking back to services, articles linking to both. Crawlers and humans use the same signal: what you link to is what you claim matters.
If you want to see where a site currently stands before committing to a rebuild, the website authority checker gives you a baseline in a few seconds, and the 12-month SEO roadmap covers what to do with the answer.
Auth, proxy and multi-tenancy
Three areas where architecture decisions are hardest to reverse:
Authentication. Sessions belong in httpOnly cookies, verified on the server. Do the real authorisation check in the data layer, as described above — a check in the UI is a user experience nicety, not a security control. And know which routes are dynamic because they read the session, because that decision cascades into your caching.
The proxy layer. Next.js 16 renamed middleware.ts to proxy.ts, running on the Node.js runtime, to make the network boundary explicit. It's the right place for redirects, locale and tenant resolution, and cheap session presence checks — and the wrong place for database queries or heavy authorisation logic, because it runs on every matched request including asset requests.
Multi-tenancy. Decide early whether tenants are separated by subdomain, path or header, and how tenant identity flows from the request to the query. Retrofitting tenant isolation onto a single-tenant schema is one of the most expensive migrations in application software — I've done it, and I'd rather charge a client for two extra days at the start than two months later. This is a core consideration in SaaS and platform builds and across the industries where one product serves many organisations.
The six ways Next.js architectures go wrong
Almost every problem I'm called in to fix is on this list:
"use client"too high in the tree. One directive in a root layout turns a server-rendered app into a single-page app with extra steps. Symptom: a large first-load bundle on every route, including the ones with no interactivity.- Calling your own API routes from Server Components. An HTTP round trip to your own process. Symptom: mysterious latency and duplicated error handling.
- No caching plan. Either nothing is cached and the server bill scales with traffic, or something personal is cached and users see each other's data. Symptom: both, in the same codebase.
- God layouts. Providers, analytics, a chat widget and a state store in the root layout, paid for on every page. Symptom: the blog is as heavy as the dashboard.
- Data access scattered everywhere. Queries and permission checks copied between pages. Symptom: a security fix that has to be applied in nine places, and you find the tenth in an incident.
- No observability. No error tracking, no real-user monitoring, no log aggregation. Symptom: you learn about outages from customers, and you debug performance with opinions instead of data.
The last one is worth dwelling on, because it's the cheapest to fix and the most often skipped. Error tracking, structured logs and real-user Core Web Vitals cost very little to wire up and change how every subsequent decision gets made. Without them, "the site feels slow" is an argument. With them, it's a number with a cause attached.
 A team arranging ideas on a glass wall — architecture is mostly a set of agreements, which is why the conventions have to be written down somewhere a new developer will actually find them
What good architecture costs
Architecture isn't a separate line item you can decline. It's how the work is done — and doing it properly costs less than doing it twice. Realistic 2026 ranges for work I'd sign my name to:
| Scope | Range | Timeline |
|---|---|---|
| Marketing site, static-first, SEO and schema complete | ₹1.2–3.5 lakh (~$1.4k–$4.2k) | 3–6 weeks |
| Content platform or e-commerce front end with a CMS | ₹3–8 lakh (~$3.6k–$9.6k) | 6–10 weeks |
| Web application — auth, dashboard, real data model | ₹4–12 lakh (~$4.8k–$14k) | 8–16 weeks |
| Multi-tenant SaaS or internal platform | ₹10–30 lakh (~$12k–$36k) | 4–8 months |
| Architecture review and remediation of an existing app | ₹60,000–2.5 lakh (~$720–$3k) | 1–4 weeks |
Add 15–20% of build cost annually for dependency updates, framework upgrades, monitoring and the small fixes that keep a codebase from rotting. A fuller breakdown of what drives these numbers is in what a website costs in 2026, and if you're still deciding whether a custom build is the right call at all, custom versus WordPress versus no-code is the honest comparison — including the cases where I'd tell you not to hire a developer yet.
The expensive path isn't the thorough build. It's the cheap build followed eighteen months later by a rescue project, which typically costs more than the original and comes with a live user base you can't switch off while you fix it.
Migrating an existing app without stopping the business
Most of this work isn't greenfield. It's an existing site — a WordPress build that's outgrown itself, a client-rendered SPA that search engines can't read, a Pages Router app that needs to move forward — and the business can't pause while you rebuild.
The answer is never a big-bang rewrite. It's the strangler pattern, applied route by route:
- Audit first (week one). Inventory every route, its traffic, its conversions and its current performance. You'll usually find that twenty percent of routes carry ninety percent of the value. That's your order of work.
- Stand up the new app alongside the old one. A proxy routes specific paths to the new application and everything else to the existing system. Users never see a boundary.
- Move the highest-value routes first. Usually the home page and the top three landing pages. You get the performance and SEO benefit immediately rather than at the end.
- Migrate the data layer before the UI. Define your queries and authorisation in the new architecture, and let the old UI consume them if it can. This de-risks the hard part while the visible part is unchanged.
- Keep URLs identical, or redirect permanently. This is where migrations lose rankings. Every changed URL needs a 301, and the mapping is written before launch, not discovered afterwards in Search Console.
- Cut over and monitor. Watch error rates, Core Web Vitals and organic traffic for a fortnight with the ability to route back instantly.
For a Pages Router to App Router move specifically, the two routers coexist in one application, so you can migrate a route at a time over months. There's no reason to take a flag day. If you're weighing whether a migration is worth it at all, signs you need custom software covers the triggers that actually justify it — and if the honest answer is that your current site is fine and the problem is traffic, I'd rather tell you that than sell you a rebuild.
 Someone arranging cards on a wall to plan a sequence of work — migrations succeed or fail on ordering, not on technology
Making it hold up with more than one developer
Architecture that only exists in one person's head isn't architecture. The things that make it durable are unglamorous:
- A written conventions file in the repository. Where things go, what gets cached, when
"use client"is allowed, what a page file may contain. Fifty lines beats fifty pages. - TypeScript in strict mode, end to end, from schema to component props. Types are the cheapest documentation that can't go out of date.
- Tests where the risk is — the data layer, authorisation, money and anything with business rules. Not every button.
- CI that enforces the rules: type check, lint, build, bundle budget. A convention that isn't checked is a preference.
- Observability from day one, as above.
- Dependency hygiene. Framework and library updates on a schedule, in small increments. A Next.js app two major versions behind isn't stable, it's accruing interest.
That last point matters more in this ecosystem than most. Next.js moves quickly — Turbopack became the default bundler, caching was redesigned around Cache Components, middleware.ts became proxy.ts, params became async. None of these are hard to absorb in the month they ship. All of them are painful to absorb three years late, all at once, which is exactly what happens to codebases nobody maintains. It's also why keeping up with the stack is part of the job rather than a hobby.
Frequently asked questions
What is a Next.js architecture? It's the set of decisions that determine how a Next.js application renders, fetches, caches and organises code — specifically: the rendering strategy for each route, where the server/client boundary sits, how data access and authorisation are centralised, and what gets cached and how it's invalidated. Folder structure is the visible result of those decisions, not the decisions themselves.
What is the best folder structure for a Next.js app?
Group by feature, not by file type, once a project passes a handful of files. Keep app/ for routing only (pages, layouts, loading, error, not-found), put one folder per business capability in features/ with its own components, data access and schemas, keep genuinely generic primitives in components/ui/, and keep infrastructure in lib/. Add two rules: colocate until something is shared twice, and no cross-feature imports.
Should I use the App Router or the Pages Router in 2026? The App Router, for anything new. It's where Server Components, streaming, Cache Components and all current framework development live. The Pages Router still works and doesn't need an emergency migration, but it's no longer receiving the architectural improvements — and because both routers run in the same application, an existing Pages Router app can migrate one route at a time rather than all at once.
When should a component be a Client Component?
When it needs state, effects, event handlers, browser-only APIs, or a library that requires them. The important part is where you mark it: "use client" creates a boundary, and everything imported below it ships to the browser. Put the directive on the smallest possible leaf, keep pages and layouts as Server Components, and pass server-rendered content into client wrappers as children rather than importing it inside them.
How should caching work in Next.js 16?
Caching is explicit and opt-in now. Enable Cache Components in your config, mark cacheable pages, components or functions with "use cache", set lifetimes with cacheLife profiles, label entries with cacheTag, and invalidate with revalidateTag(tag, profile) when the underlying data changes — or updateTag in a Server Action when the user needs to see their own write immediately. Never cache anything session-dependent, and invalidate on the write rather than on a timer.
Is Next.js good for SEO? Yes, and it's one of the strongest reasons to choose it — but only if the architecture uses it. Server rendering means crawlers get complete HTML, and the framework provides per-route metadata, generated sitemaps, structured data and dynamic Open Graph images. A Next.js app where every page is client-rendered behind a loading spinner gets no SEO benefit at all, which is a depressingly common way to buy the framework and not use it.
How do I stop a Next.js app from getting slower over time?
Enforce a first-load JavaScript budget in CI so regressions fail the build, keep the root layout minimal, audit third-party scripts quarterly, review every new "use client" in code review, and monitor real-user Core Web Vitals rather than lab scores. Slowness is never one commit — it's fifty small ones nobody measured.
Do I need a separate backend with Next.js? Usually not. Server Components, Server Actions and route handlers cover the API needs of most applications, and a single deployable codebase is cheaper to run and reason about. A separate backend earns its place when you have non-HTTP workloads, long-running jobs, multiple client applications sharing one API, a different language requirement, or a team structure that genuinely needs the split. Adding one "for scale" before any of those are true buys complexity and nothing else.
How long does it take to build a Next.js application? Three to six weeks for a static-first marketing site with complete SEO, six to ten weeks for a content or commerce front end, eight to sixteen weeks for a real web application with authentication and a data model, and four to eight months for multi-tenant SaaS. Schedules slip on integrations and content far more often than on framework work.
Can you migrate my existing site to Next.js without losing rankings? Yes, if the URL mapping is written before launch rather than discovered afterwards. Keep URLs identical where you can and issue permanent redirects where you can't, migrate the highest-traffic routes first, preserve titles, metadata and structured data, and monitor Search Console and traffic closely for a few weeks with the ability to route back. Rankings are lost in migrations through carelessness with URLs, not through changing frameworks.
What does an architecture review involve? A week or so of reading the codebase and measuring it: bundle composition per route, the rendering strategy actually in use versus the one intended, where the client boundary sits, how data access and authorisation are structured, the caching model, Core Web Vitals from real users, and the dependency and upgrade position. The output is a written document — what's wrong, what it costs you, what to fix first, and what to deliberately leave alone. It's often the cheapest useful thing a team with an existing app can buy.
Do you work with clients outside Kashmir? Yes. A good part of my work is for clients elsewhere in India and abroad, and the process runs over calls and shared documents exactly as it would across a desk. Building from Srinagar means everything I ship is designed for the connectivity and devices we actually have here, which turns out to be a useful constraint anywhere.
 Two developers reviewing code together at a desk — the conventions above only work if someone is accountable for them after launch, not just during the build
The short version
A Next.js architecture is worth having because it's the difference between a codebase that gets cheaper to change and one that gets more expensive. Concretely:
- Choose a rendering strategy per route and write the choice down.
- Keep the client boundary at the leaves, and treat every new
"use client"as a bundle decision. - Give data one front door, with authorisation inside it.
- Make caching explicit, tag-invalidated, and never personal.
- Structure by feature, keep
app/for routing, and forbid cross-feature imports. - Treat performance and SEO as architecture, measured in CI and in production, not audited at the end.
- Migrate incrementally. Nothing good comes from a flag day.
Get those right and Next.js is genuinely excellent — fast by default, pleasant to work in, and cheap to extend. Get them wrong and you have a React SPA with a build step and a server bill.
If you have an existing Next.js app that feels slower than it should, or you're about to start one and want the four decisions made deliberately rather than by accident, tell me what you're building and what's not working. I'll come back with an honest assessment: what I'd change, what I'd leave alone, what it would cost and how long it would take — and if the right answer is that your current setup is fine and your problem is elsewhere, I'll tell you that instead of quoting you for a rebuild.
Ready sooner? Request a quote with your requirements, see what I build and the systems behind it, or read what clients have said about working this way.
Owais Noor
Full-Stack Developer & Digital Marketer, based in Srinagar. I write about building fast, useful websites and software — and getting them found.